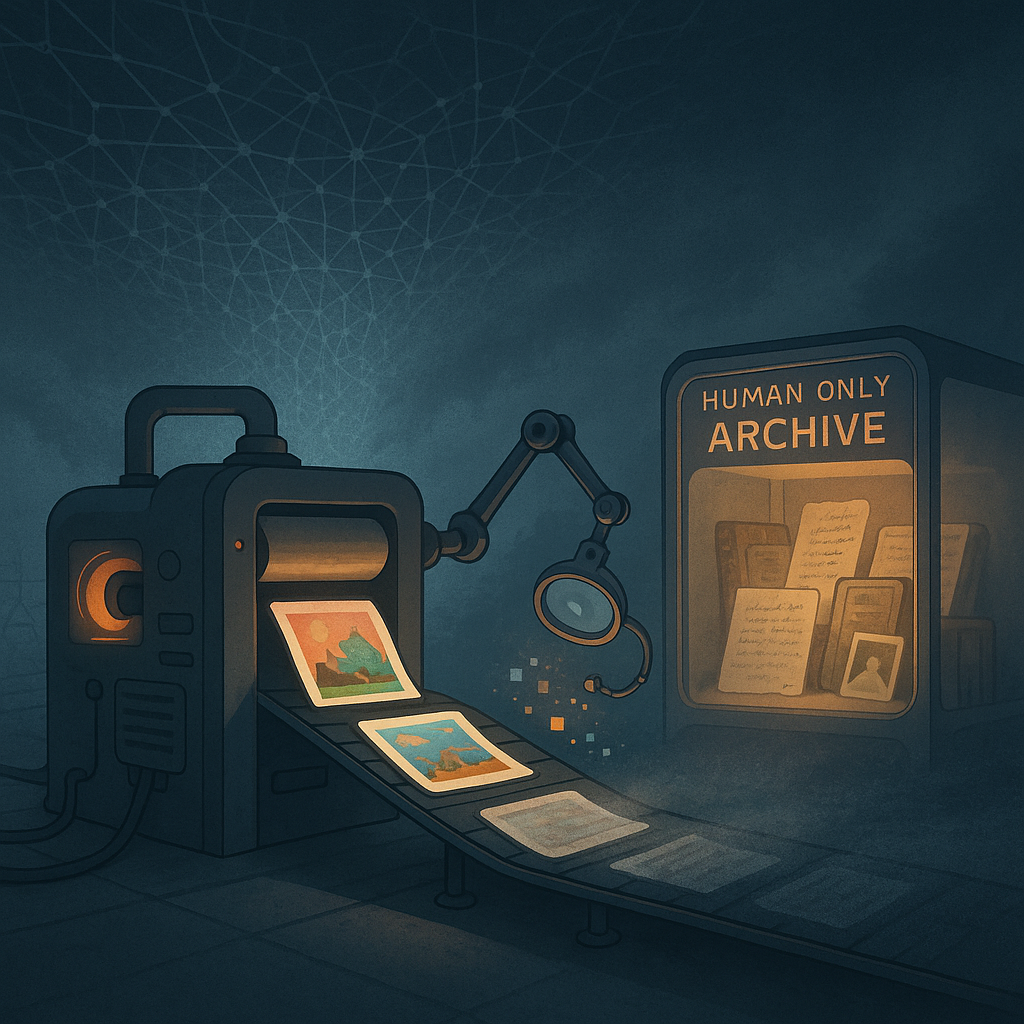
A quiet but unsettling question is bubbling up among AI researchers: could the growing flood of AI‑generated content on the internet make future AI systems worse? The July 28, 2023 Scientific American article explores this possibility and introduces the term “model collapse” (sometimes framed in public discussion as “AI will eat itself”): the idea that when successive generations of models are trained—even partially—on synthetic outputs from earlier models, errors and artifacts can compound until model outputs degrade.
What the experiments show
Researchers have run controlled experiments that make the danger concrete, even if only in simplified settings. Ilia Shumailov and colleagues observed collapse in small language and image models (for example, experiments with OPT‑125m) and in a toy model that separated two probability distributions: after repeated rounds of training on synthetic outputs, errors accumulated until outputs became effectively meaningless. Rik Sarkar and collaborators ran similar tests with diffusion image models: the first model produced recognizable images (flowers and birds), but later‑generation models trained on those synthetic images yielded increasingly blurred, lower‑quality results.
Important context: these experiments were carried out on relatively modest models and simplified setups rather than the largest commercial foundation models. That limitation means the results are a serious warning but not definitive proof that the same fate will befall large, heterogeneous training pipelines used in production.
Why this happens (and why it matters)
The mechanism is straightforward and alarming: when synthetic content replaces human‑created content in training datasets, statistical artifacts, hallucinations and biases from earlier models get baked into the next generation. Over recursive cycles, those artifacts amplify because models are learning from outputs that reflect prior models’ distortions rather than fresh human signals. The consequences include a loss of richness and diversity in model outputs (especially for rare or “tail” cases), worsened representation for marginalized groups, and the amplification of errors.
The article uses a vivid analogy to radioactive contamination of steel after nuclear tests: once contamination spreads into a large source of training material, finding “untainted” data later becomes extremely difficult.
How synthetic content is already leaking into training data
The piece notes several realistic vectors by which AI‑generated content could creep into future training corpora:
– Newsrooms and websites publishing AI‑generated articles.
– Crowdsourced annotation platforms, where annotators sometimes use language models to produce or summarize answers (experiments have found Mechanical Turk responses that resembled ChatGPT outputs).
– Community knowledge resources such as Wikipedia, where some contributors have proposed using language models to generate content.
Because these channels feed the web and data repositories that model builders draw on, synthetic content can enter training pipelines even when it is not intentionally included.
Possible mitigations—and their limits
Researchers and commentators offer several short‑term ideas to slow or prevent model collapse:
– Curate and preserve “human‑only” datasets—collections that can be verified as human‑produced and used as high‑quality training material.
– Develop and deploy tools to detect and filter synthetic content before it becomes part of training sets.
– Change annotation workflows and platform rules to discourage or prevent annotators from submitting model‑generated outputs as supposed human annotations.
The article is careful to stress that these are proposed or exploratory measures rather than proven fixes. Detection is technically difficult, particularly in blurred cases where humans edit model outputs. There’s no easy, field‑tested recipe yet for preventing contamination at internet scale.
Uncertainties the piece emphasizes
The Scientific American article is clear about what remains unknown. Most demonstrations of model collapse use smaller models and controlled setups, so researchers cannot yet say how vulnerable large commercial foundation models are when trained on vast, heterogeneous data. The article does not identify a simple numeric threshold (for example, “X% synthetic data causes collapse”)—experiments suggest even small fractions can matter in toy settings, but how this scales in practice is unresolved. And importantly, the article does not claim inevitability or immediate catastrophe; several researchers say the issue “may become a consideration in a few years” as synthetic content proliferates.
Where this leaves us
The article offers a sober, middle‑path takeaway: model collapse is a real risk demonstrated in experiments, and the internet already contains channels that could let synthetic content contaminate future datasets. But there is uncertainty about how the problem will play out at production scale and no off‑the‑shelf solution yet. That combination—evidence of a mechanism, early experimental confirmation, practical vectors for contamination, and an absence of proven large‑scale fixes—makes this an urgent area for further research, careful data stewardship, and thoughtful platform policy.
If you’re a developer, policymaker, or data curator, the article suggests two immediate, practical moves: start preserving and curating verified human‑only datasets now, and rethink annotation and platform rules so they don’t inadvertently onboard model‑generated content as ground truth. Beyond that, researchers need to test the phenomenon on larger models and to develop more robust detection and filtering tools. The longer‑term health of the AI ecosystem may depend on whether we treat synthetic‑data contamination as a solvable engineering problem—or ignore it until the models we rely on begin to learn from their own echoes.
Leave a Reply